Architecture & Platform

Cloud Business Continuity — Designing for the Loss of a Region

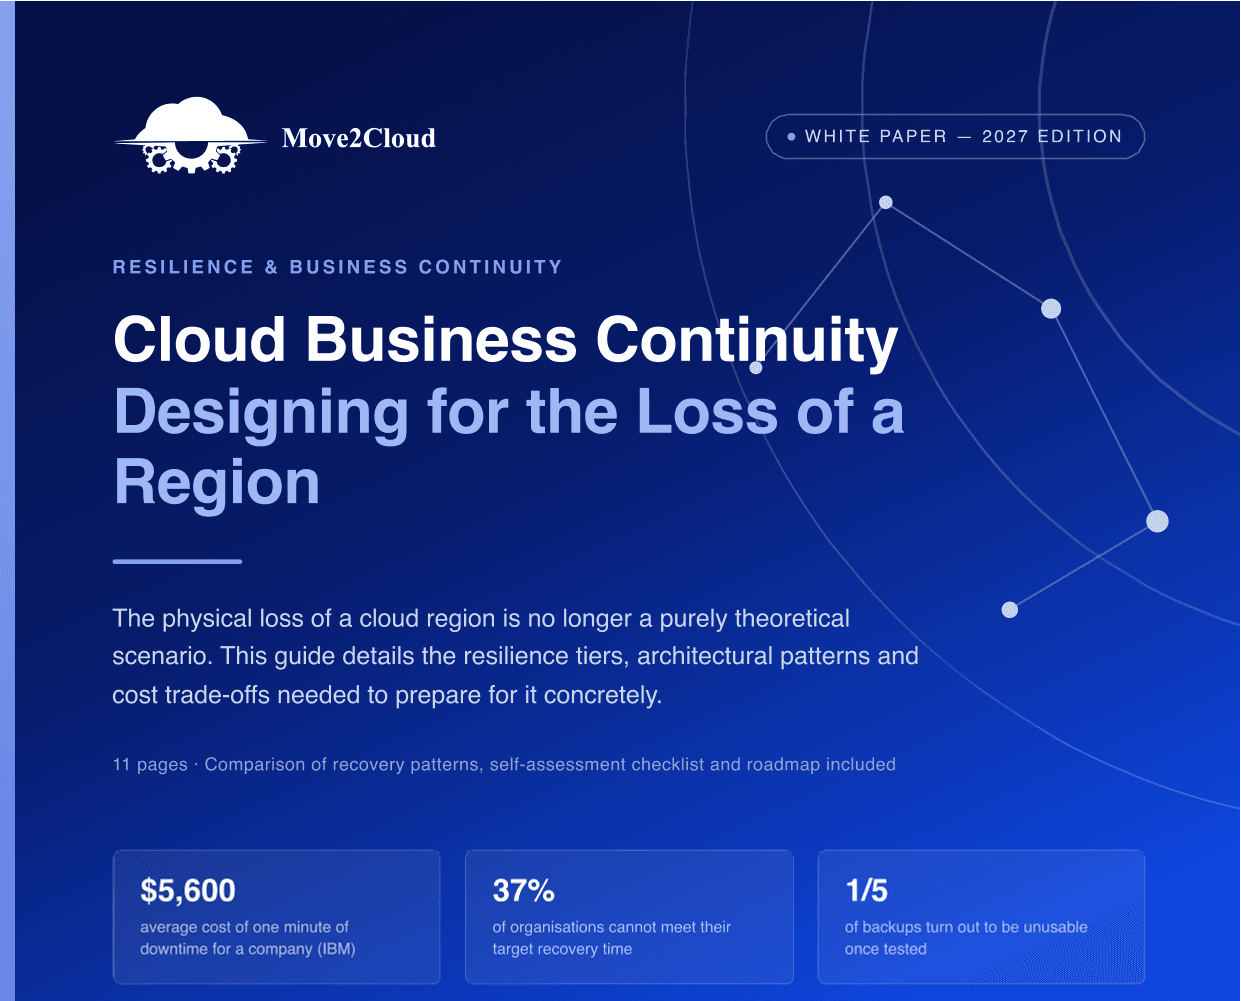
The physical loss of a cloud region is no longer a purely theoretical scenario. This guide details resilience levels, architectural patterns, and cost trade-offs to prepare for it concretely.

September 2026

In March 2026, physical damage to several data centers of a major cloud provider in the Middle East caused the loss of multiple availability zones and degraded more than a hundred services across an entire region.

37% of organizations say they cannot meet their target recovery time, and one backup in five turns out to be unusable when actually tested. Downtime costs a business an average of $5,600 per minute.

RTO, RPO, and the four levels of continuity

Four levels help reach target RTO and RPO, from simplest to most costly: backup/restore (hours to days), pilot light (tens of minutes), warm standby (minutes), and active-active multi-site (near zero).

An RTO and RPO are only meaningful once verified through a real failover exercise.

Multi-zone doesn't replace multi-region

Spreading a workload across multiple availability zones within the same region protects against the failure of an isolated data center — not against an event that affects the region as a whole.

The two resilience levels address different risks and don't substitute for one another.

Key takeaways

  • Know the RTO and RPO actually achievable for critical services
  • Replicate critical backups to a geographically distinct region
  • Have run a real failover exercise within the last twelve months
  • Match each service's continuity level to its real business criticality
  • Automate failover rather than relying on manual intervention
YOUR GUIDE TO KEEP

Cloud Business Continuity — Designing for the Loss of a Region

Get the complete guide to explore the topic further and share best practices with your team.

Download the PDF

Free PDF · Direct access

Ready to put it into practice?

Our experts help you move your cloud projects forward.

Go further

Running a Cloud Migration Programme: Framing, Business Case, PMO and GovernanceCloud

Running a Cloud Migration Programme: Framing, Business Case, PMO and Governance

Framing, business case, AMOA/PMO roles, governance cadence and change management: how to run a cloud migration programme that doesn't fail for non-technical reasons.

OpenTelemetry: Distributed Traces and Observability in ProductionKubernetes & Conteneurs

OpenTelemetry: Distributed Traces and Observability in Production

OpenTelemetry has become the cloud-native observability standard. Traces, metrics and logs unified in a single SDK — learn how to implement it in production with Grafana Tempo.

Model Context Protocol (MCP): Connecting AI to Your DevOps ToolsCI/CD & GitOps

Model Context Protocol (MCP): Connecting AI to Your DevOps Tools

Anthropic's Model Context Protocol standardises how LLMs access tools and data. Learn how to build MCP servers to automate your DevOps workflows.